Microsoft’s final report on the outage that took down Outlook: a dormant bug, tests on old servers and safeguards that spread the failure
Microsoft has published its final report on the near 24-hour Microsoft 365 outage that cut off Outlook and Teams worldwide, including for South African businesses and government. It says a bug dormant since July hit only newer gateway servers, its tests used older machines, and automatic failover spread the problem to every region.
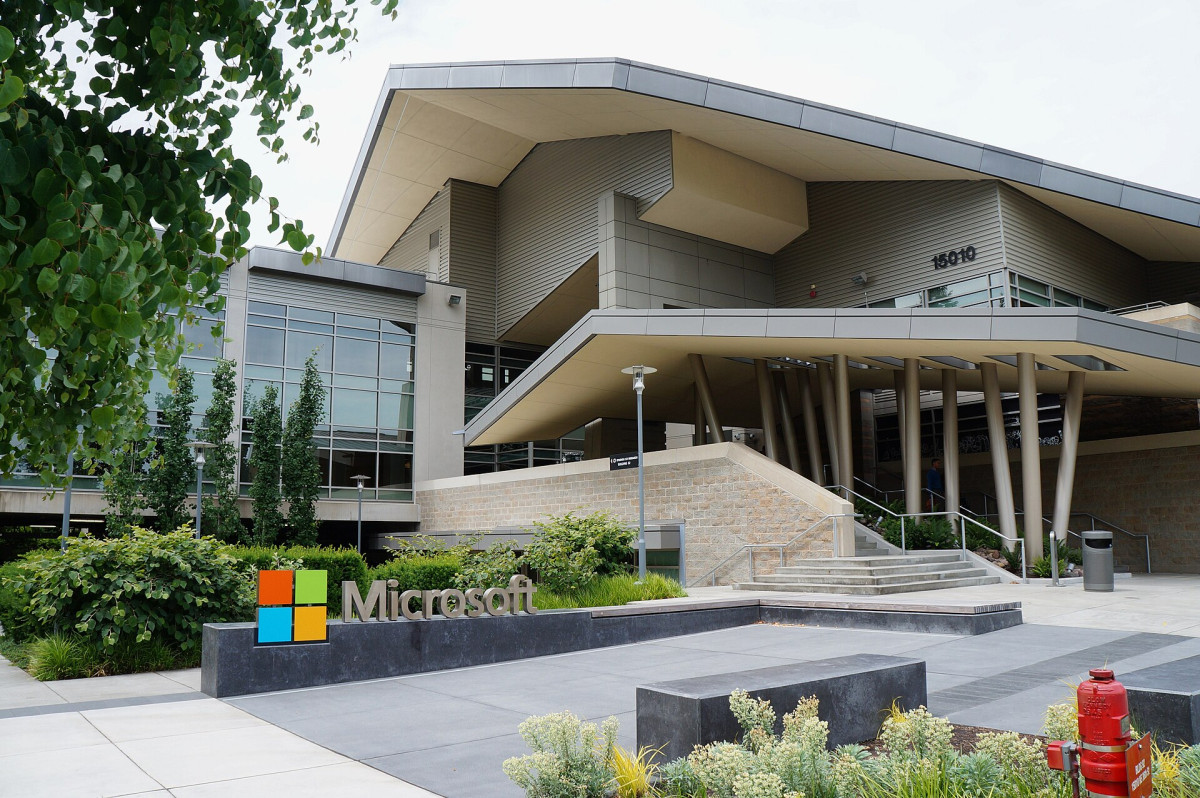
Microsoft has published its final explanation of last week’s global Microsoft 365 outage, which knocked out Outlook email, Teams and other services for close to a day and disrupted offices, universities and government departments in South Africa and around the world.
The report, released on Friday evening US time and detailed by GeekWire, admits that the company’s own testing missed the fault: “Our testing did not adequately represent the combination of hardware and traffic mix encountered during this incident.”
A bug that waited since July
The problem sat in Microsoft’s network gateway, the servers that act as the front door to Outlook and other Microsoft 365 services. A Windows update used only on those servers, rolled out from July, changed how they handled incoming connections. Under heavy load, tasks got stuck waiting on one another until servers ran out of memory and computing power.
The fault hit only newer, more powerful servers, because they try to do more at once. Microsoft’s load tests ran on older, lower-core machines, so the bug went unnoticed for more than three months.
Three things lined up
According to the report, three conditions came together on the day:
- About 14% of gateway capacity was offline for routine updates.
- A routing glitch about 15 hours earlier in the US East region had moved all of Teams’ worldwide traffic onto the servers that handle email.
- Traffic then climbed as the North American workday began.
Safeguards that made it worse
As servers froze, automatic systems shifted their traffic to healthy servers that carried the same bug, which then failed too. At the worst point more than 80% of gateway servers in North America were unresponsive, and within about two hours servers in every region were affected. Servers that came back were swamped by pent-up demand and froze again, a pattern engineers call a “thundering herd”.
The report lists 13 follow-up steps. These include testing on hardware that matches production by the end of March, keeping failures from crossing between regions, separating email capacity so a surge from Teams cannot take it down, failing Teams over only in the affected region, and easing traffic back onto recovering servers gradually. Some fixes do not yet have dates.
Microsoft says no business email was lost, although some delayed messages to consumer mailboxes inactive for more than 30 days bounced. It repeated that the outage was not a cyberattack and was not caused by AI tools. Chief executive Satya Nadella told the company’s Ignite conference this week that it had “work to do” on resilience.
The South African impact
In South Africa the outage dragged on for more than 18 hours, TechCentral reported at the time, with organisations including SARS, the City of Cape Town, universities and airlines reporting disrupted email and workplace tools. The City of Cape Town published a notice telling residents how to reach it while its email was down.
Related: FBI investigates apparent hack of the NCIC database | Ekurhuleni’s CCTV registration order faces legal pushback
Sources
- GeekWire — Microsoft’s final Outlook outage report details testing gaps and safeguards that backfired
- GeekWire — What went wrong with Outlook: Microsoft blames ‘thundering herds’ and a bug unnoticed for months
- TechCentral — Microsoft outage drags past 18 hours, hitting SA companies hard
- City of Cape Town — Global Microsoft outage: Friday, 13 November 2026
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0
The Republic Times newsroom: independent, ad-free South African journalism. Story tips and corrections: info@republictimes.co.za.






Comments (0)